Updated November 2026.
TL;DR
- Control Plane is the best overall cloud disaster recovery solution. Workloads fail over automatically across regions and clouds. The 99.999% availability SLA applies to workloads running at least two replicas in at least two locations. During the October 2025 AWS outage, affected workloads were active and running in healthy locations within 10 seconds, according to Control Plane internal incident telemetry.
- Native hyperscaler DR tools (AWS Elastic Disaster Recovery, Azure Site Recovery) suit single-cloud teams, but only recover into their own cloud and failover is operator-initiated.
- Replication-based DRaaS (Zerto, Veeam) fits VM-heavy, on-premises estates with active-passive standby.
- Developer PaaS platforms don’t document automatic cross-provider failover.
Most disaster recovery plans are designed to survive infrastructure failures, such as a zone going down or a region becoming unavailable, but assume the cloud provider itself stays up. That assumption fails more often than engineering teams expect. Control Plane’s cloud outage tracker logs 62 major AWS, Azure, Google Cloud, and Cloudflare outages since 2020, with a median duration of 6 hours 8 minutes (as of November 2026). When it does, the difference between a team that keeps running and a team writing incident reports is whether disaster recovery was an architectural default or a runbook nobody had tested.
This piece is the vendor-comparison companion to our technical guide. For the full breakdown of RTO/RPO tiers, failover patterns, and implementation, see Cloud disaster recovery strategies, RTO/RPO targets, and best practices. Here the focus is buyer-facing: which cloud disaster recovery platforms and approaches are available today, evaluated against the criteria a CTO or platform team uses during vendor selection: how fast recovery happens, how automatically it happens, and whether it survives losing an entire cloud provider as well as a single availability zone.
How we evaluated these
Each option was scored on four questions:
- Does failover survive a full provider outage, or only a zone or region failure inside one cloud?
- Is recovery automated (health-aware routing that reacts in seconds) or operator-initiated (a recovery plan a person starts under pressure)?
- What RTO/RPO tier does it realistically support (hours, minutes, or near zero)?
- What does it cost to run, in infrastructure spend and in team effort to build and maintain it?
The four DR topology patterns and their cost
Cloud DR strategies fall into four postures, Backup and Restore, Pilot Light, Warm Standby, and Multi-Site Active-Active, with different RTO/RPO outcomes and cost profiles. The table below is a quick orientation; for how each pattern works and how to choose between them, see the technical guide linked above.
| Pattern | Typical RTO | Typical RPO | Always-on cost |
|---|---|---|---|
| Backup and Restore | Hours | Hours | Minimal (storage only) |
| Pilot Light | Tens of minutes | Minutes | Low (minimal standing infrastructure) |
| Warm Standby | Minutes | Minutes | Moderate (partial idle infrastructure) |
| Multi-Site Active-Active | Seconds | Near zero (synchronous) to seconds (asynchronous) | No dedicated standby; every site serves traffic, plus failover headroom |
The ranking
1. Control Plane: best overall, with automatic cross-cloud failover built in
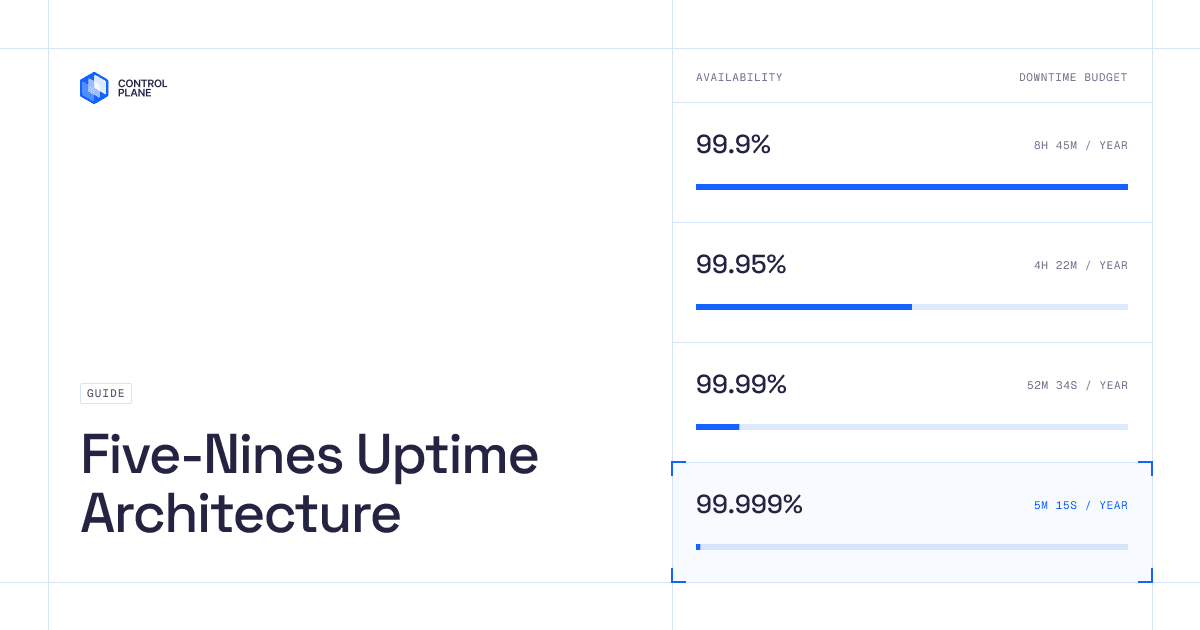
Control Plane’s disaster recovery model is Unbreakable Compute: if an entire region or cloud provider fails, workloads fail over automatically to surviving regions or other clouds with no human intervention. The 99.999% availability SLA applies to workloads running at least two replicas in at least two locations, and allows a maximum of about 5 minutes 15 seconds of downtime a year.
During the October 20, 2025 AWS outage, which began in us-east-1, ran roughly 15 hours, and disrupted more than 100 AWS services, 20 percent of Control Plane customers had an AWS us-east-1 location in their Global Virtual Cloud (GVC), Control Plane’s deployment target that spans multiple regions and clouds. Failover was automatic: affected workloads were active and running in healthy locations within 10 seconds, with no customer downtime, according to Control Plane internal incident telemetry (Beyond Backups).
How it works: a GVC spans regions across AWS, GCP, and Azure, GPU neoclouds, and infrastructure you own as one deployment target, connected by a single mutual-TLS network. Universal Cloud Identity, Control Plane’s credential-free cloud access layer, gives workloads access to 600+ services across AWS, GCP, and Azure with no long-lived cloud keys in your code, so failing over between those providers does not require rebuilding your identity and access model. For GVC configuration and health-based routing details, see the technical guide.
Compute and data fail over together: Control Plane runs stateful workloads alongside stateless ones in the same GVC, and ships multi-location Postgres and Redis templates that automatically promote a replica in a surviving location; automatic failover needs three or more locations so a majority remains (Control Plane docs). Compute failover takes seconds; RPO follows the replication mode you choose for each database.
Why teams choose this over building it themselves: most engineering teams build active-active and cross-provider failover incrementally, under pressure, after something has already broken. Control Plane ships active-active, cross-provider failover, a single mutual-TLS network, and cross-cloud identity as platform defaults, so none of it becomes a second infrastructure project. Control Plane also handles Day 2 operations, including autoscaling, Capacity AI (Control Plane’s right-sizing of CPU and memory based on historical usage), built-in observability, and security, with no Kubernetes cluster to operate. Customers typically cut compute costs 30 to 50 percent compared with running directly on AWS, GCP, or Azure.
Customer proof point: SAFE Health, a digital health and connected-diagnostics platform operated in partnership with the Mayo Clinic, moved off AWS-only infrastructure: “We migrated 8 environments from AWS to Control Plane and no one noticed! Everything just worked.” Their engineering leader added that while they run on multiple AWS regions today, “with Control Plane adding GCP regions is trivial. It’s a switch.” (case study)
Compliance: SOC 2 Type II, PCI DSS Level 1, HIPAA, and GDPR, with one control set across every location, which matters when disaster recovery is evaluated alongside an audit requirement.
Best for: teams that want active-active compute and data across regions, on one cloud or several. Teams concentrated on a single hyperscaler get provider-level failover as headroom.
Other options worth knowing
These are the realistic alternatives buyers evaluate, with a side-by-side comparison at the end of this section.
Developer platforms and PaaS (such as Render and Railway) cover build, deploy, and managed databases on one platform. Most offer database backups, and some offer high-availability database failover. Render’s Postgres high availability, for example, fails over automatically to a standby in a separate zone of the same region (Render). They are built around deploying to regions you choose, and their documentation does not describe a single workload that fails over automatically from one cloud provider to another. For teams whose requirement is surviving the loss of an entire provider, that is the gap that matters.
Native hyperscaler DR tools (AWS Elastic Disaster Recovery, Azure Site Recovery) recover servers into their own provider’s regions and can replicate from on premises or other clouds. AWS cites RPOs of seconds and RTOs of minutes for Elastic Disaster Recovery (AWS). They only recover into their own cloud, so AWS Elastic Disaster Recovery cannot fail you over to GCP or Azure, and failover is operator-initiated rather than automatic (Microsoft). The October 20, 2025 incident began in one region and still broke console sign-in and IAM-dependent services in other AWS regions (AWS), which shows how far one provider’s shared dependencies reach. These tools suit teams firmly on one cloud and stop being sufficient once losing the whole provider becomes a real question.
Traditional replication-based DRaaS (Zerto, a Hewlett Packard Enterprise company, and Veeam) continuously replicates VMs to a standby site or a service provider’s cloud and runs orchestrated recovery plans, reaching RTO in minutes and RPO in seconds for replicated VMs (Zerto). Veeam pairs Continuous Data Protection with Veeam Recovery Orchestrator, which runs automated failover runbooks (Veeam). It fits VM-centric warm-standby postures in enterprises with significant on-premises infrastructure. It was not designed for containerized, multi-region active-active architectures: failover is an active-passive event someone initiates, and you pay for standby capacity.
Comparison at a glance
| Criteria | Control Plane | Developer PaaS | Native hyperscaler DR (AWS EDR / Azure Site Recovery) | Traditional DRaaS |
|---|---|---|---|---|
| Survives a full provider outage | Yes, automatic cross-cloud failover | No automatic cross-provider failover documented | No, recovers only into its own cloud | Yes, to a standby replica site (active-passive) |
| Failover trigger | Automatic, health-aware geo-routing (seconds) | Varies; high-availability database failover on some platforms | Operator-initiated (one click or API) | Orchestrated recovery plan, typically operator-initiated |
| Best RTO tier supported | Seconds (active-active) | Varies; generally not published | Minutes | Minutes (replicated VMs) |
| Best RPO tier supported | Near zero, set by replication mode | Varies by database and backup settings | Seconds to 5 minutes | Seconds (replicated VMs) |
| Identity across clouds | Universal Cloud Identity: credential-free access to 600+ services across AWS, GCP, and Azure | No cross-cloud identity layer | Native to one provider | Not applicable |
| Data portability / vendor lock-in | Low: standard containers portable across supported clouds | Moderate to high: tied to the platform’s regions and services | High: tooling and recovery target are provider-specific | Moderate: depends on replication target |
| Cloud-native / containerized workloads | Yes, built for containerized workloads across clouds | Yes, container-first | Partial: best for VM-based servers | Limited: designed for VM workloads |
| Compliance certifications | SOC 2 Type II, PCI DSS Level 1, HIPAA, GDPR | Varies by platform | Broad certifications, scoped to one provider | Varies by vendor |
| Pricing model | Reserved CPU and memory, billed per millicore and megabyte, with no contracts or minimums; no idle standby in active-active | Per-service or per-resource pricing | Per protected server (AWS lists $0.028 per source server hour as of November 2026) plus replication storage and recovery compute | Per-VM or per-GB replication fees plus standby infrastructure |
| Best fit buyer | Teams needing automatic cross-region or cross-cloud DR with no manual failover | Teams wanting one platform for build, deploy, and databases in chosen regions | Teams firmly on one cloud needing zone or region resilience | Enterprises with significant on-premises or VM-based workloads |
Related reading
- The best multi-cloud failover solutions in 2026
- How to build active-active high availability across regions and clouds
- Five nines uptime architecture: what single-region, multi-region, and multi-cloud designs can deliver
- AWS outage, one year later: lessons from every cloud failure
- What is high availability, and how many nines you actually need
FAQ
What’s the difference between backup and disaster recovery?
Backup protects data. Disaster recovery restores service. A backup with no automated way to bring the application back online on other infrastructure leaves your team executing a manual recovery under pressure, and that recovery is what determines your RTO, or how long you are down.
Is cloud-based disaster recovery better than on-premises?
Cloud DR usually wins on elasticity, since you are not paying for permanently idle standby hardware, and on how quickly you can add failover regions. On-premises DR offers direct control over data locality. Control Plane removes the either-or choice: you can keep specific workloads on premises or in a specific jurisdiction while the rest fail over automatically across AWS, GCP, and Azure.
Can disaster recovery span multiple cloud providers automatically?
Yes, on platforms built for it. Native hyperscaler DR tools recover only into their own cloud. Cross-cloud DR needs a layer such as Control Plane’s Global Virtual Cloud, which treats regions on multiple providers as one deployment target with a single network and identity model, so failover becomes a traffic-routing change the platform handles automatically. For configuration details, see the technical guide.
What RTO and RPO should I target?
Set RTO and RPO per workload tier. Customer-facing production systems usually justify warm standby or active-active, with RTO and RPO from minutes down to near zero. Internal tools and batch jobs are often fine with pilot light or backup and restore. For a full workload-tiering framework, see the technical guide.
Does multi-region deployment alone protect against a provider-wide outage?
Partly. Multiple regions inside one cloud protect against a regional failure, and during the October 20, 2025 AWS incident most workloads outside us-east-1 kept serving. The same incident still broke console sign-in and IAM-dependent services in other AWS regions, because those depend on us-east-1. Spreading locations across providers removes that shared dependency on one provider’s global services. For a step-by-step plan, see how to keep your app online when an AWS region goes down.
What is DRaaS, and how is it different from backup?
Disaster recovery as a service (DRaaS) replicates whole servers or applications to standby infrastructure and brings them up there during an outage. Backup only stores copies of data for a later restore, so recovery from backup alone usually takes hours while someone rebuilds infrastructure and restores data. DRaaS tools such as Zerto, Veeam, AWS Elastic Disaster Recovery, and Azure Site Recovery cut recovery to minutes, but failover is still an event an operator starts. On an active-active platform such as Control Plane, every location already serves traffic, so there is no separate recovery step.
What is the difference between RTO and RPO?
RTO (recovery time objective) is how long a service can be down before it is restored. RPO (recovery point objective) is how much data, measured in time, you can afford to lose. Backup and restore typically delivers RTO and RPO in hours, replication-based DR delivers minutes and seconds, and active-active with synchronous replication delivers RTO in seconds and RPO near zero.
How much does cloud disaster recovery cost?
Cost follows the DR pattern. Backup and restore costs little beyond storage. Pilot light and warm standby add standing infrastructure that sits mostly idle, and DRaaS tools add per-server fees: AWS Elastic Disaster Recovery lists $0.028 per source server hour, about $20 a month per server, plus replication servers, storage, and snapshots (as of November 2026). Active-active needs no dedicated standby because every location serves traffic, though each location needs headroom to absorb a failed one. On Control Plane, you pay for the CPU and memory each workload reserves, with no contracts or minimums, and customers typically cut compute costs 30 to 50 percent compared with running directly on AWS, GCP, or Azure. For a worked comparison, see active-active vs active-passive: the real cost of multi-region high availability.
See automatic multi-cloud failover on your own workload: Book a demo